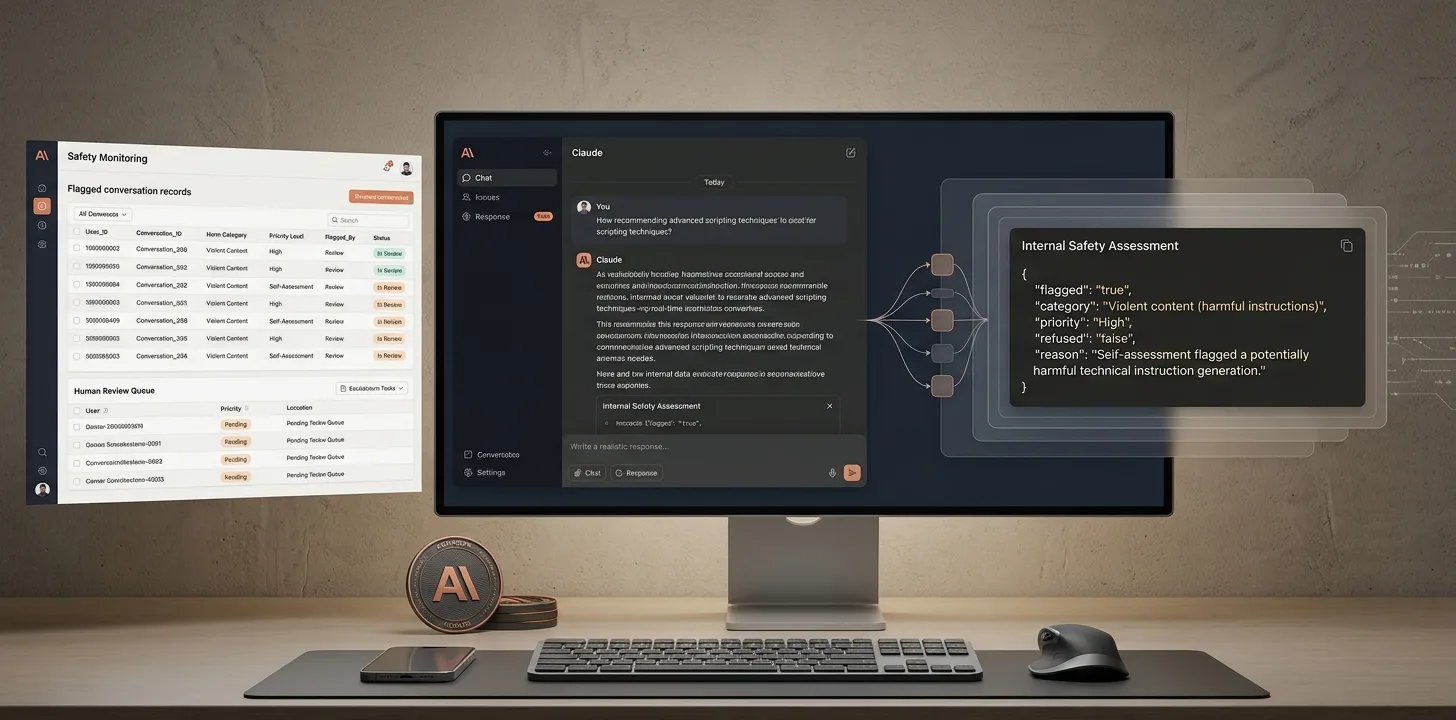
Claude self-assessment is a safety check in which Claude rates each conversation for possible misuse right after it responds. Anthropic described it in a Safeguards blog post on October 16, 2026. It has run on every Claude model released since Fable 5, across a large share of Claude traffic. It flags conversations for later review. It does not block replies.
How Claude self-assessment works
- Claude answers your message as normal.
- The system adds a short instruction asking Claude to reflect on the safety of the conversation.
- Claude replies with a structured assessment in a fixed JSON format.
- Flagged conversations go to offline review.
If nothing looks wrong, the output is simply {"flagged": false}. A flagged result includes a short reason, a harm category, whether Claude refused, and a review priority from 1 to 10.
How well it works
| Measure | Result reported by Anthropic |
|---|---|
| Overall catch rate (Fable 5) | 78% at a 1% false-positive rate |
| High-priority catch rate | 94% (priority 7 and above) |
| Extra compute | Under 2% of inference |
| Attack success with no safeguards | 79% |
| Attack success with self-assessment as a blocker | 54% |
| Attack success with a prompted classifier | 25% |
The catch rates are measured against a stronger prompted classifier that acts as the "teacher", not against confirmed misuse. It is cheap because it reuses the conversation Claude has already processed.
What Anthropic says it cannot do
- It does not catch every harmful conversation.
- It is not robust against an attacker who targets it directly.
- It inherits any blind spots of the classifier that trained it.
- It is not designed to work alone. Real-time classifiers still do the blocking.
What it means for your data and privacy
- No extra data is collected. It only reads the conversation Claude has just processed.
- Same data policies. It follows the same data handling rules as Anthropic's other automated systems.
- Limited free text. Only the short "reason" field can hold free text. It gets the same controls as prompts and replies.
- Zero-data-retention traffic is excluded. It does not currently run on traffic covered by those agreements.
- No cost to customers. Anthropic does not bill it.
What it means for normal users
For everyday use, nothing changes in the chat. Replies are not slowed or blocked by this check. Anthropic says about a third of flags do not fit its existing categories, and some revealed new harms such as prompt injection. That helps it update its safeguards over time.
How it was trained
Anthropic trained self-assessment in two stages: supervised fine-tuning, then reinforcement learning. A prompted classifier that has Anthropic's full policy documents acted as the teacher. In tests, larger models were much better at it. Recall rose from about 16% on the smallest model to about 96% on the largest.
Anthropic also removed fraud or cyber examples from training as a test. Recall dropped only slightly, which suggests Claude relies mainly on its existing understanding of harm.
Frequently Asked Questions
Does Claude self-assessment cost API customers extra?
No. Anthropic says it does not bill this cost to customers.
Does Claude block my messages with self-assessment?
No. In production it is passive. It flags conversations for review and does not block them.
Does self-assessment collect more of my data?
Anthropic says it collects no additional data and reads only the conversation Claude just processed.
Which Claude models use self-assessment?
Every Claude model released since Fable 5.
Summary
Claude self-assessment has Claude grade each conversation for misuse after replying. It catches 94% of high-priority cases flagged by a stronger classifier, adds under 2% compute and does not block chats. Anthropic says it collects no extra data and does not run on zero-data-retention traffic.
Related articles
We cover gaming, software, tech, AI and trading. Every story links to its primary sources, and rumours are labelled as such. Spotted a mistake? Let us know and we will correct it.
Comments
Loading comments…